Greta Hoffmann · 14 October 2026
Exploring Interconnected Data Pathways That Drive Outcome Prediction in Resource Monitoring Frameworks
Resource monitoring frameworks rely on networks of sensors, databases, and analytical tools that collect measurements from physical assets, digital logs, and environmental variables. These measurements travel along multiple pathways that intersect at processing nodes, where algorithms combine inputs to forecast future states such as equipment wear, energy demand, or material depletion. Data indicates that when pathways share common variables, small changes in one stream can propagate through others and alter overall prediction accuracy.
Data Collection and Initial Routing
Modern frameworks begin with distributed sensors that record temperature, pressure, flow rates, and usage metrics at regular intervals. Information moves first to edge processors that filter noise and attach timestamps before forwarding packets to central repositories. According to documentation from the U.S. Environmental Protection Agency, standardized metadata tags allow downstream systems to trace each reading back to its origin without requiring manual reconciliation. Researchers have observed that frameworks using consistent tagging reduce latency between collection and first-stage analysis by measurable margins.
Once inside the repository, data enters routing layers that direct subsets toward different analytical engines. One engine might handle short-term anomaly detection while another builds longer-range trend models. The choice of route depends on priority flags attached during collection, and those flags themselves update when new context arrives from parallel streams. This dynamic routing creates the first layer of interconnection that later supports outcome prediction.
Interconnections Among Processing Nodes
Processing nodes exchange intermediate results through shared message queues and common data schemas. A model predicting water reservoir levels, for instance, may receive updated evaporation estimates from a climate module at the same time it receives consumption forecasts from a demand module. The two inputs combine at a fusion node that recalculates probability distributions for the coming weeks. Evidence from studies published by the European Environment Agency shows that such fusion steps improve forecast precision when the underlying pathways carry correlated variables rather than independent ones.
Pathway density increases when frameworks incorporate external feeds such as market prices or regulatory updates. These feeds arrive through API endpoints that map incoming values onto internal variable names. Observers note that mismatches in units or reference dates can break downstream calculations unless automated converters sit at each junction. In October 2026 several monitoring platforms adopted unified conversion libraries released by international standards bodies, and initial deployment logs recorded fewer route failures after the change.
Outcome Prediction Mechanisms
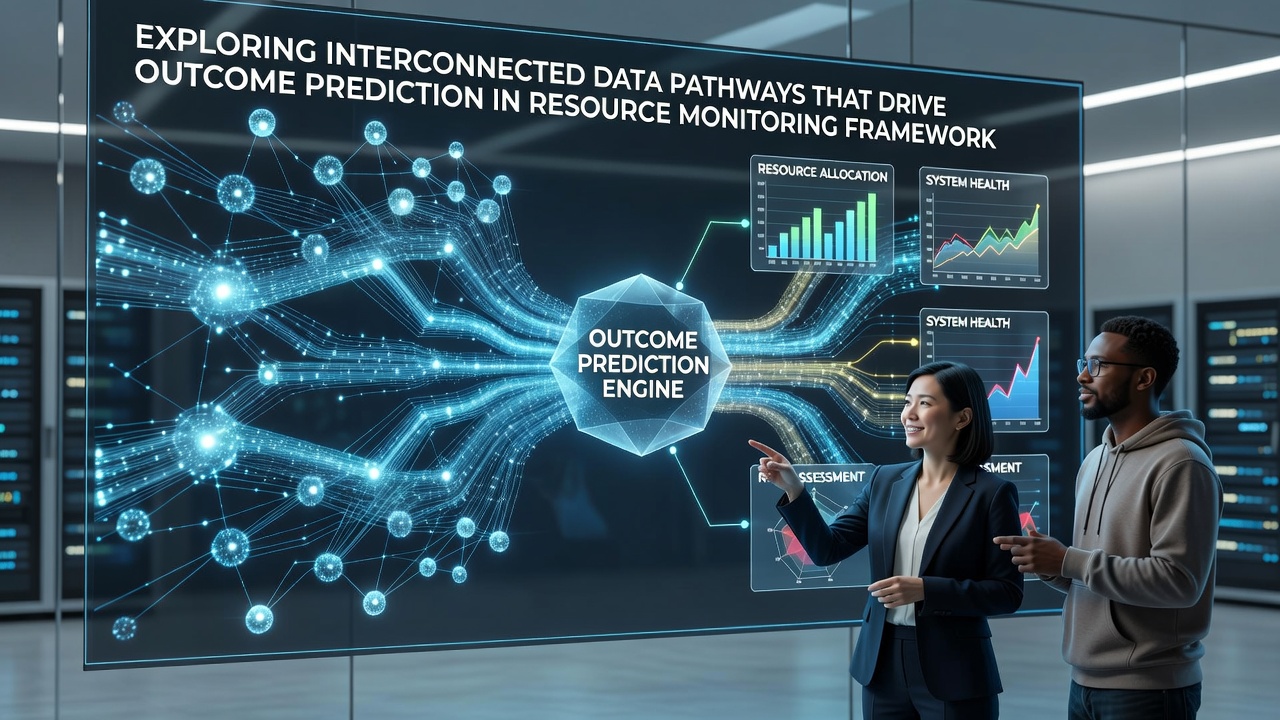
Prediction engines apply statistical and machine-learning techniques to the merged datasets. Regression models estimate linear relationships while recurrent neural networks capture temporal dependencies across multiple time scales. When pathways converge on the same target variable, ensemble methods weight each contribution according to historical performance. Data released by Natural Resources Canada indicates that ensembles drawing from at least three distinct pathway clusters consistently outperform single-source models in long-term resource allocation tasks.
Feedback loops close when prediction outputs feed back into operational controls. A system forecasting fuel consumption might adjust valve settings or reorder logistics schedules, and the resulting measurements travel back along the same pathways to refine the next cycle. This closed loop turns static monitoring into adaptive management. Those who have examined production logs from large-scale deployments report that loop stability depends on keeping latency low across all intersecting routes.
Scaling and Maintenance Considerations
As the number of monitored assets grows, pathway counts multiply and require additional indexing structures. Graph databases have emerged as practical tools for mapping which nodes connect to which streams. Administrators use these maps to identify single points of failure and to plan capacity upgrades. Industry reports from the Australian Bureau of Statistics highlight that organizations maintaining explicit pathway inventories experience shorter recovery times after hardware faults compared with those relying on ad-hoc documentation.
Security practices also evolve with pathway complexity. Encryption applies at each hop, and access controls limit which analytical engines can read sensitive streams. When external links are involved, data-sharing agreements define retention periods and audit rights. Frameworks that document these agreements alongside technical diagrams reduce compliance review effort during periodic assessments.
Conclusion
Interconnected data pathways form the structural backbone of outcome prediction inside resource monitoring frameworks. Collection points feed routing layers, processing nodes exchange intermediate results, and prediction engines synthesize outputs that influence operational decisions. Continued refinement of metadata standards, conversion libraries, and graph-based inventories supports reliable scaling while preserving traceability across all routes.